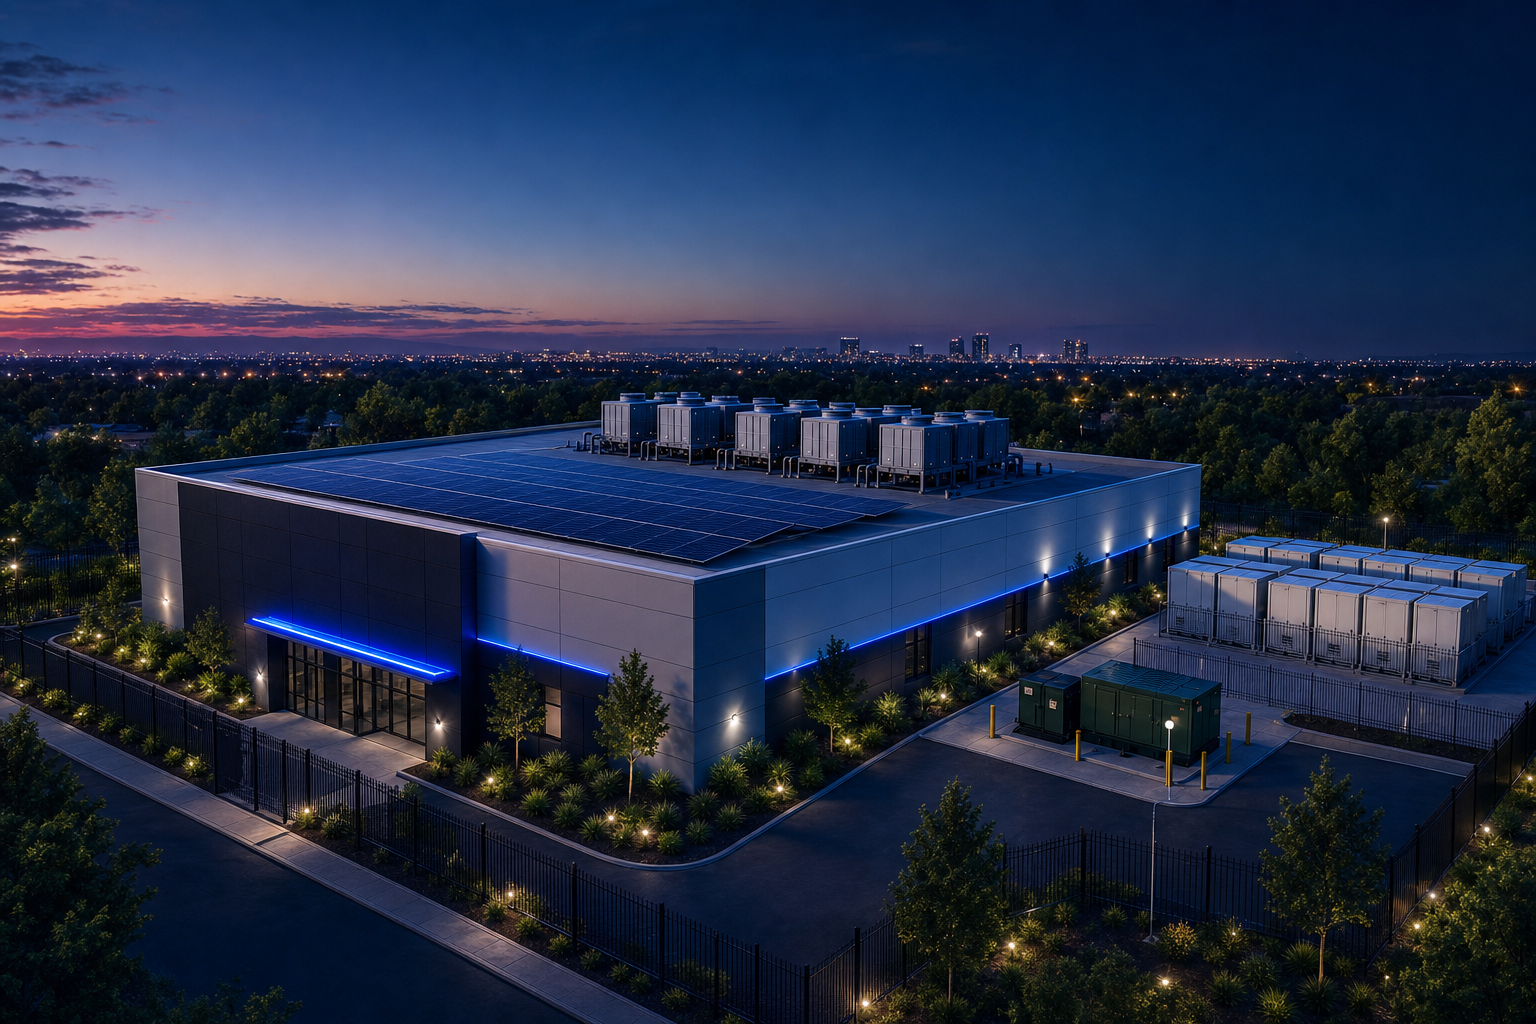
160 MW first. 30+ sites behind it.
Our first four sites deliver 160 MW of total compute, contracted and in development. Behind them, more than 30 additional sites are in development across Tier 1 U.S. markets, each delivering 5–10 MW of grid-connected power inside the population centers that generate the data and consume the intelligence. Every site is co-located with our fiber, delivered in under 10 months, and quantum-secure at every layer of the network.
Four sites delivering 160 MW. More than 30 behind them.
Our first four sites deliver 160 MW of total compute and are contracted and in development. Behind them is a deep pipeline of more than 30 additional sites in development across Tier 1 U.S. markets, each delivering 5–10 MW of grid-connected power — placed where inference demand already lives, and delivered in under 10 months per site.
Total compute, contracted and in development.
In development across Tier 1 U.S. markets.
Grid-connected power.
From executed lease, per site.
The bottleneck moved from raw compute to placement.
Training rewards centralization. Inference punishes it. As inference becomes the dominant AI workload, the constraint is no longer how many GPUs exist — it is how far the answer has to travel.
Distance you cannot optimize away.
Round-trip time to a distant region is bounded by the speed of light in glass. Interactive inference, autonomous systems, and real-time decisioning need compute in the metro — not two time zones away.
Workloads that cannot leave.
Healthcare, financial, defense, and critical-infrastructure data is increasingly bound by jurisdiction and policy. Distributed sites keep processing inside the boundary where the data was generated.
A deep bench beats one moonshot.
A 5–10 MW grid-connected site can be powered, permitted, and energized on timelines a multi-gigawatt campus cannot. A pipeline of 30+ sites in primary markets turns a decade-long megaproject into a repeatable build delivered in under 10 months.
Geo-located where the demand already is.
Every site in the fleet is co-located with GENIOS fiber and GENIOS power — engineered for ultra-low-latency inference and sovereign workloads.
GPU-as-a-Service
High-density GPU capacity delivered as a service for AI-native training and inference — provisioned at the edge, close to demand.
Low-latency inference
Inference sites placed where data is generated — financial services, healthcare, AV fleet hubs, and AI-native workloads.
Sovereign & secure
Air-gappable, secure-by-design architecture for sovereign inference, defense AI at the tactical edge, and IC-partner compute.
One fleet, not a collection of islands
Every site is orchestrated as a single pool of capacity — workloads placed, shifted, and failed over across the fleet rather than stranded in one building.
Same site profile. Same delivery model.
One infrastructure platform serving both commercial AI and mission-relevant workloads — running on the GENIOS technology moat.
- AV fleet hubs — profile customer in active dialogue
- Financial-services low-latency inference
- Healthcare and life-sciences AI workloads
- AI-native model training and inference
- Sovereign inference for sensitive workloads
- Defense AI at the tactical edge
- IC partner co-located compute
- Critical-infrastructure resilience (energy, water, transport)
Four layers of proprietary software — built so the platform is defensible, redundant, and mission-grade by default.
Our orchestration software, already built.
Workload placement, multi-tenant isolation, and capacity arbitrage across GENIOS Edge sites — built in-house, in deployment, extensible to every future site.
Site-to-site fabric with built-in failover.
Proprietary design and software that augments data transiting between GENIOS sites — engineered for system redundancy and risk mitigation against power-disruption events.
Caching and delivery at the inference edge.
Proprietary CDN architecture co-located with GENIOS Edge compute and fiber — the same redundancy and resilience model applied to content and model-artifact delivery.
Quantum-secure across every layer.
Quantum-secure encryption keys embedded across orchestration, SDWAN, and CDN — end-to-end, from edge endpoint to AI factory. Eliminates key transmission and harvest-now-decrypt-later risk.
We don't distribute keys. So there is nothing to intercept.
Conventional encryption — including post-quantum algorithms — still transmits a key across the wire. Anything transmitted can be captured today and decrypted later, once quantum computing matures. Our network removes that exposure at the root.
Identical keys, generated independently at each end.
Instead of sending a key from one endpoint to another, both endpoints independently generate the same key from pools of quantum-derived random numbers. The key never crosses the network, so capturing the traffic yields nothing to decrypt later.
Defending data with a long secrecy life.
Adversaries are already storing encrypted traffic to break once quantum capability arrives. For medical records, financial positions, infrastructure telemetry, and defense data, secrecy must outlive the encryption protecting it today.
One security architecture, end to end.
The same quantum-secure key architecture runs from edge devices and sensors through our transit fabric into the GPU infrastructure doing the inference — not bolted onto one hop while the rest of the path stays conventional.
Ahead of the federal mandate, not chasing it.
Federal policy now sets firm post-quantum deadlines for encryption and authentication, and agencies are migrating well before them. Tenants landing on our fabric inherit a quantum-secure posture instead of retrofitting one under a deadline.
Quantum-secure key generation is delivered in partnership with a specialist cryptography provider and is embedded across the GENIOS orchestration, SDWAN, and CDN layers.
Energy resilience, engineered in from day one.
Behind-the-meter generation, storage, and EV charging built into every site we deliver.
Fleet-grade per site.
Demand-charge management and resilience.
Reduces utility draw.
Direct interconnect; pre-screened substation capacity.